S3 Managed Tables, Unmanaged Costs: The 20x Surprise with AWS S3 Tables
From the trenches: Managing Apache Iceberg metadata for near-real-time workloads
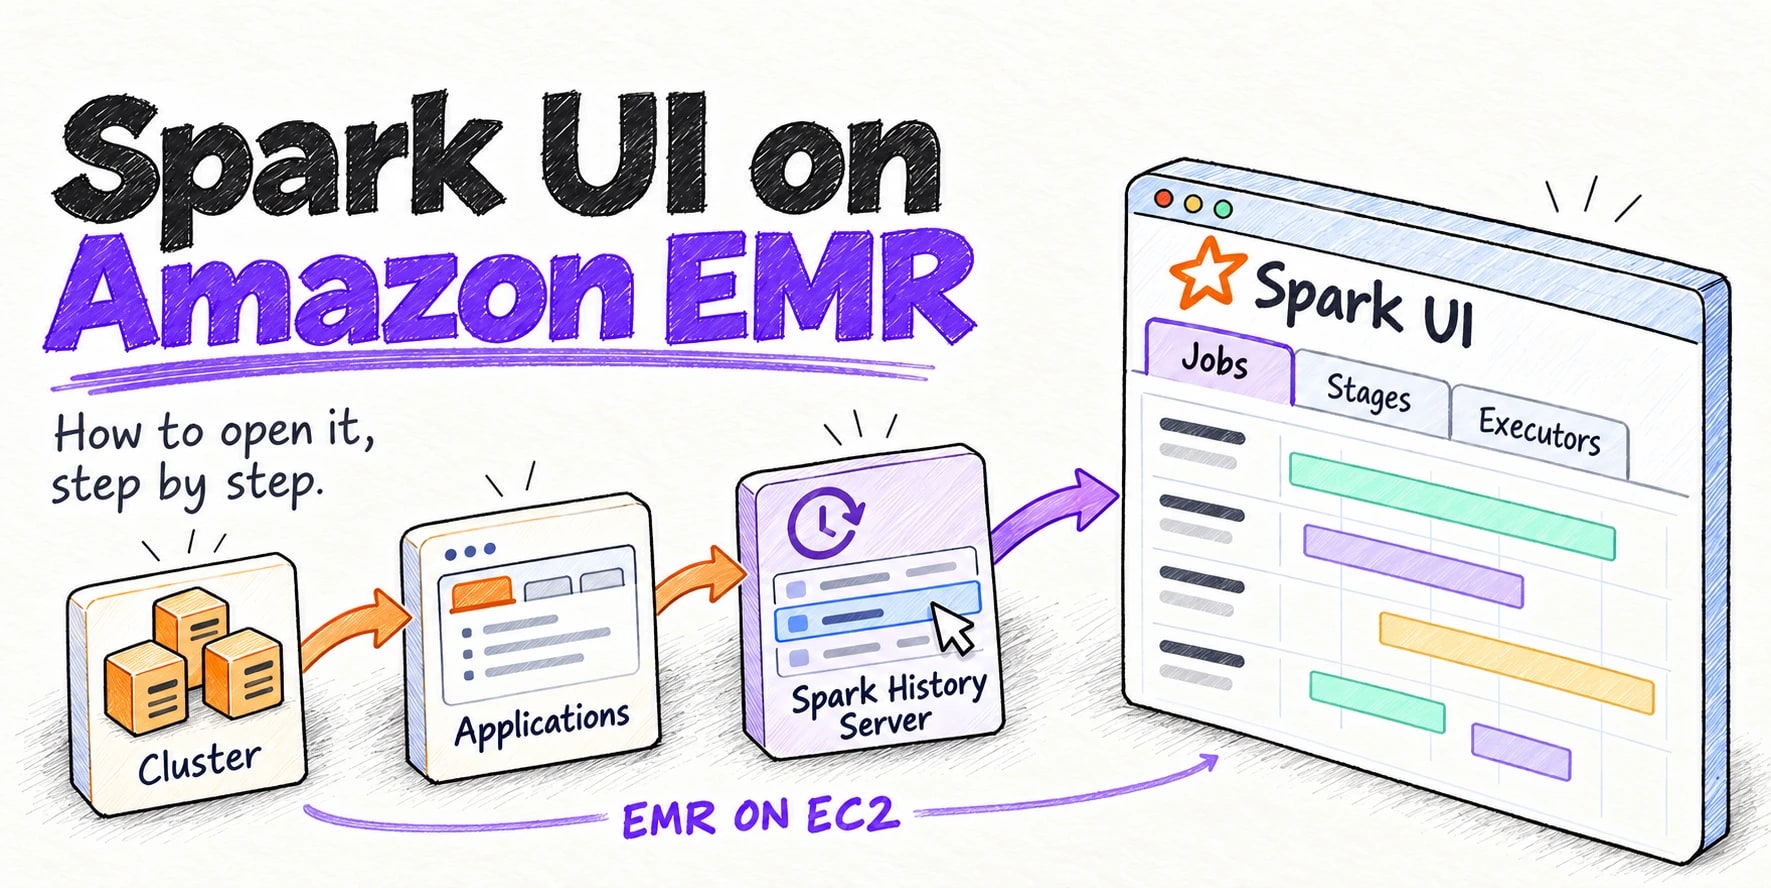
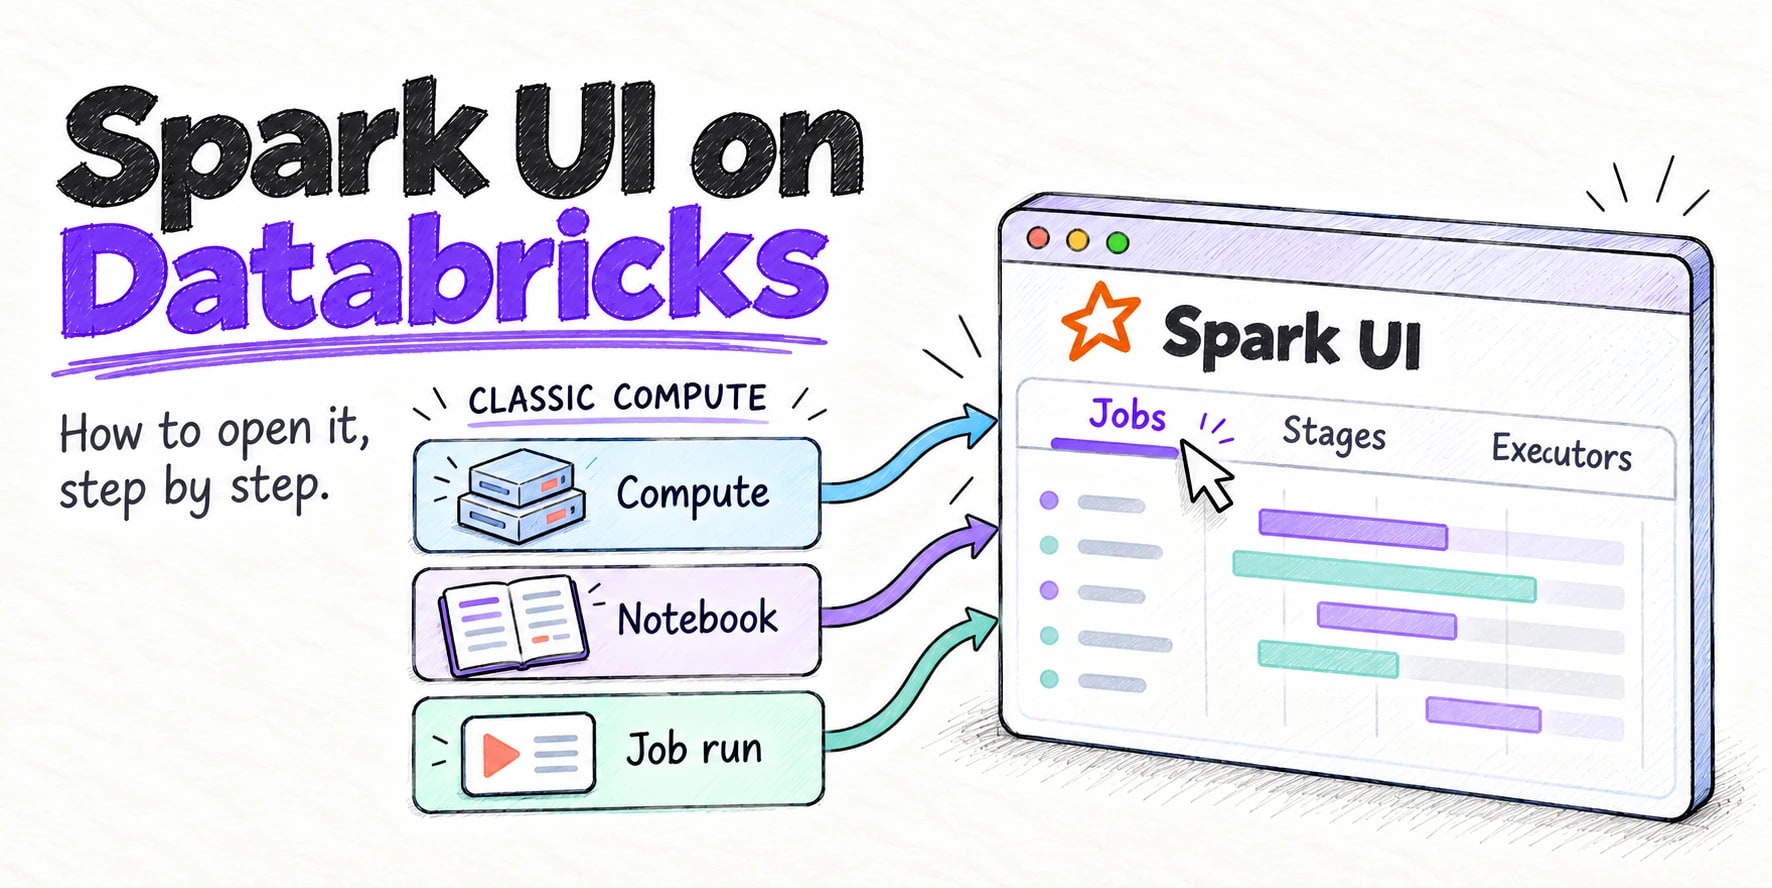
Announcing Apache Spark™ and SQL on the Onehouse Compute Runtime with Quanton
Measuring ETL Price-Performance On Cloud Data Platforms
Towards Open Data - Part 1: Cloud Warehouses Now Love Open Formats
Announcing Open Engines™: Flipping defaults to “open” for both data and compute
Apache Flink™ vs Apache Kafka™ Streams vs Apache Spark™ Structured Streaming — Comparing Stream Processing Engines
ClickHouse vs StarRocks vs Presto vs Trino vs Apache Spark™ — Comparing Analytics Engines
Ray vs Dask vs Apache Spark™ — Comparing Data Science & Machine Learning Engines
Data Deduplication Strategies in an Open Lakehouse Architecture
The Open Table Format War: Merely a Battle on the Path to Engineering a Truly Open Data Platform
ACID Transactions in an Open Data Lakehouse
Using Apache Hudi™ Data with Apache Iceberg™ and Delta Lake
Moving Beyond Lambda: The Unified Apache Beam Model for Simplified Data Processing
What is Clustering in an Open Data Lakehouse?
Introducing Onehouse Compute Runtime to Accelerate Lakehouse Workloads Across All Engines
Accelerating Lakehouse Table Performance - The Complete Guide
Unbundling Your Data Platform: How Open Data Lakehouses are Changing the Game
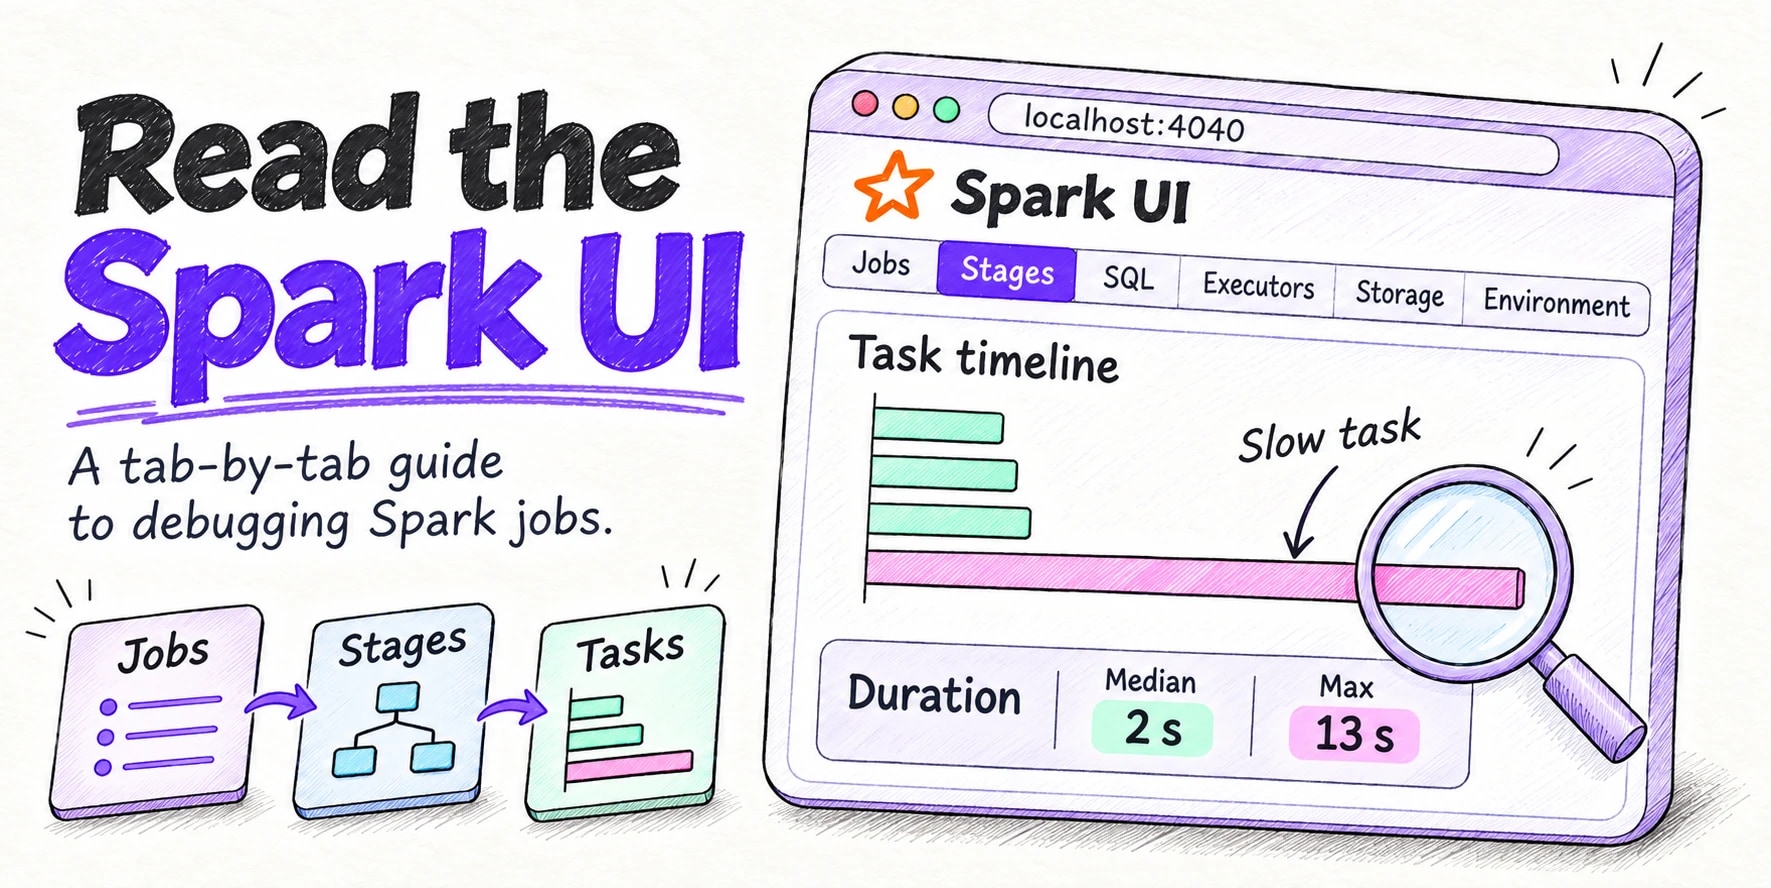
Top 5 tips for scaling Apache Spark™
Amazon S3 Data Lakes: A Complete Guide
Data Infrastructure Transformation at Scale: Conductor's Success with Onehouse
Introducing LakeView Insights and New Deployment Models
Comprehensive Data Catalog Comparison
AWS re:Invent Recap 2024: AI & Open Table Formats
Open Source Data Summit 2024 Draws Data Engineers and Data Architects
How to Optimize Performance for Your Open Data Lakehouse
Conductor Unlocks the Power of Open Data Architectures with Onehouse
Leveling Up the Data Lakehouse with LakeView and Table Optimizer
Open Table Formats and the Open Data Lakehouse, In Perspective
Why Data Architecture Should Guide Your Query Engine Decision
The Onehouse Data Integration Datasheet: Your Guide to Seamless Data Connectivity
Apna Unlocks AI Job Matching for 50 Million Users With Confluent & Onehouse
Table Optimizer: The Optimal Way to Execute Table Services
Breaking Free from Data Lock-In with Snowflake & Onehouse
Announcing: AI Vector Embeddings Generator for the Lakehouse
NOW Insurance Uses Data and AI to Revolutionize an Industry
Onehouse Analytics Engine Guide
Solving Data Challenges: Olameter and Onehouse Team Up for Enhanced Predictive Maintenance
Onehouse Achieves PCI Compliance Certification
Open Data Foundations with Apache XTable: Hudi, Delta, and Iceberg Interoperability
Introducing Onehouse LakeView
Introducing Onehouse Table Optimizer
Raising our Series B and Our Quest For the Most Open and Interoperable Data Platform
How to use Apache Hudi™ with Databricks
Managing AI Vector Embeddings with Onehouse
Apache Hudi™ - The Open Data Lakehouse Platform We Need
The Universal Data Lakehouse: User Journeys From the World's Largest Data Lakehouse Builders
Running Apache Hudi™ on Databricks
Announcing OneSync™ - Multi-Catalog Sync with Snowflake, Databricks, BigQuery
Optimizing JobTarget’s Data Lake: Migrating to Hudi, a Serverless Architecture, and Templated Glue Jobs
Data Warehouse vs. Data Lake vs. Data Lakehouse
Onehouse Custom Transformations QuickStart
Dremio Lakehouse Analytics with Hudi and Iceberg using XTable
Schema Evolution on the Data Lakehouse
Scaling and Governing Robinhood’s Data Lakehouse
NOW Insurance's Technical Evolution with Onehouse
Panel: OSS in Today's Data Architectures
Diving into Uber's Cutting-Edge Data Infrastructure
What is a Data Lakehouse?
Notion's Journey Through Different Stages of Data Scale
Enabling Walmart's Data Lakehouse With Apache Hudi™
Apache Hudi™ 1.0 Preview: A Database Experience on the Data Lake
Using Onehouse CDC Streaming for Real-Time Retargeting
2023: A Breakthrough Year for Onehouse and the Universal Data Lakehouse
Overhauling Data Management at Apna
Onehouse Offers First Turnkey End-to-End CDC Ingestion Lakehouse
The First Open Source Data Summit is a Hit!
OneTable is Now Open Source
On “Iceberg and Hudi ACID Guarantees”
Maximizing Change Data Capture
It’s Time for the Universal Data Lakehouse
Eliminate Tedious Data Management with Onehouse and CelerData
Lakehouse or Warehouse? Part 2 of 2
Lakehouse or Warehouse? Part 1 of 2
It’s Official: Onehouse is Now SOC 2 Type II Certified
Building a near real-time data lake with Onehouse and Starburst
Meet the Residents of Onehouse - Andy Walner!
Apply Pre-Commit Validation for Data Quality in Apache Hudi™
The Ultimate Data Lakehouse for Streaming Data Using Onehouse + Confluent
Knowing Your Data Partitioning Vices on the Data Lakehouse
The Road to an Open and Interoperable Lakehouse
Integrating Onehouse with the Amazon Sagemaker Machine Learning Ecosystem
Optimize Costs by Migrating ELT from Cloud Data Warehouses to Data Lakehouses
Exploring New Frontiers: How Apache Flink™, Apache Hudi™ and Presto Power New Insights at Scale
Building a Data Lakehouse: Managed vs. Do-it-Yourself
Onehouse's privacy first data architecture
Hudi Metafields demystified
Instantly unlock your CDC PostgreSQL data on a data lakehouse using Onehouse
Top 3 Things You Can Do to Get Fast Upsert Performance in Apache Hudi™
Powering Real-Time Analytics with Confluent Kafka and Onehouse
An Introduction to the Hudi and Flink Integration
Onehouse Product Demo - Building a data lake for Github analytics at scale
Getting Started: Incrementally process data with Apache Hudi™
Onehouse Now Available in AWS Marketplace
Getting Started: Manage your Hudi tables with the admin Hudi-CLI tool
Announcing Our Series A Funding
Announcing Onetable
Meet the Residents of Onehouse - Jeremy Crookston!
Apache Hudi™ 2022 - A year in Review
Comparing Apache Hudi's™ MOR and COW Tables: Use Cases from Uber and Shopee
How Apache Hudi™ Simplifies MPP Data Warehouse Migrations
Meet the Residents of Onehouse - Darshika Khandelwal!
Meet the Residents of Onehouse - Po Hong!
Apache Hudi™ on Microsoft Azure
Apache Hudi™ vs Delta Lake - Transparent TPC-DS Data Lakehouse Performance Benchmarks
Hudi’s Column Stats Index and Data Skipping feature help speed up queries by an orders of magnitude!
Asynchronous Indexing using Hudi
Introducing Multi-Modal Index for the Lakehouse in Apache Hudi™
Apache Hudi™ Native AWS Integrations
Hudi Sink Connector for Kafka
Automagic Data Lake Infrastructure
Introducing Onehouse
Onehouse Commitment to Openness
Onehouse 介绍
Apache Hudi™ - 2021 a Year in Review
Apache Hudi™ Z-Order and Hilbert Space Filling Curves
Data Lakehouse Concurrency Control: Are we too optimistic?
Building an ExaByte-level Data Lake Using Apache Hudi™ at ByteDance
Reliable ingestion from AWS S3 using Apache Hudi™
The text above was extracted automatically from the source page and may miss images, tables or code blocks. The original is authoritative.
Published by Hacker News
This site only summarises and aggregates; copyright stays with the original author. Headlines and summaries follow the source — where they differ, the original wins.
 Newshot