 Newshot
AI owned by everyone.
CrowdGPT is focusing on creating the world's first 0$, datacenterless and 100% open AI. Run the app on your computer, and the AI gets better.
A new paradigm for training AI.
A single company training a frontier model uses thousands of A100s in a datacenter. Most people don't have that hardware. But millions of people have gaming PCs with RTX cards sitting idle. CrowdGPT uses that compute, and the model that gets trained belongs to everyone who helped build it.
Privacy first.
Your GPU trains on 10MB data chunks streamed from the public CrowdGPT dataset on HuggingFace; a dataset anyone can inspect or contribute to. No personal files, browser history, or local data are ever accessed or transmitted.
More ecological.
Trains on consumer GPUs that are already powered on. CrowdGPT requires no new datacenters, no additional hardware manufacturing, which is a huge tradeoff of traditional AI.
Transparent.
The client is a single, human-readable Python file that anyone can audit and modify. Model weights are downloadable, 100% free and open on HuggingFace.
The client is a single open-source Python file which is human-readable. It downloads public training data online, trains locally and uploads only the model update. It cannot access your files or compromise your machine.
The server is protected too. Every update is validated for size, NaN values and norm bounds before it is cross-validated by peers, and repeat offenders are banned from the project.
Read the source before you run it.
Help the project grow.
Every contribution, even the smallest, makes the model better. Run a client, star the repo, or open an issue.
Install the client
Install everything with one command. Even if you don't have python/git installed.
- ~6 GB of free disk space. PyTorch alone is around 2.5 GB.
- A discrete GPU is strongly recommended. NVIDIA (CUDA), AMD (ROCm / DirectML), Apple Silicon (MPS) and Intel Arc (XPU) are all supported.
- A stable internet connection for streaming model weights and dataset chunks.
- CPU-only mode works, but is extremely slow.
The installer handles everything else: GPU detection, the correct PyTorch wheel, Python and Git if missing, and an isolated virtual environment.
One-line install Recommended
Copy this into your terminal. It downloads the installer, auto-detects your hardware, and starts the client.
How the installer works
- Detect hardware. Installs the right dependencies for your Graphics Card.
- Install dependencies. Python and Git are installed if missing, then PyTorch from the correct index and the project's requirements; everything is inside an isolated virtual environment so nothing touches your system Python.
- Launch. Downloads the model weights from HuggingFace, streams a dataset chunk, and starts training. You can stop at any time.
About - How it works
How CrowdGPT coordinates a bunch of independent GPUs to train a single, cohesive language model without insane infrastructure.
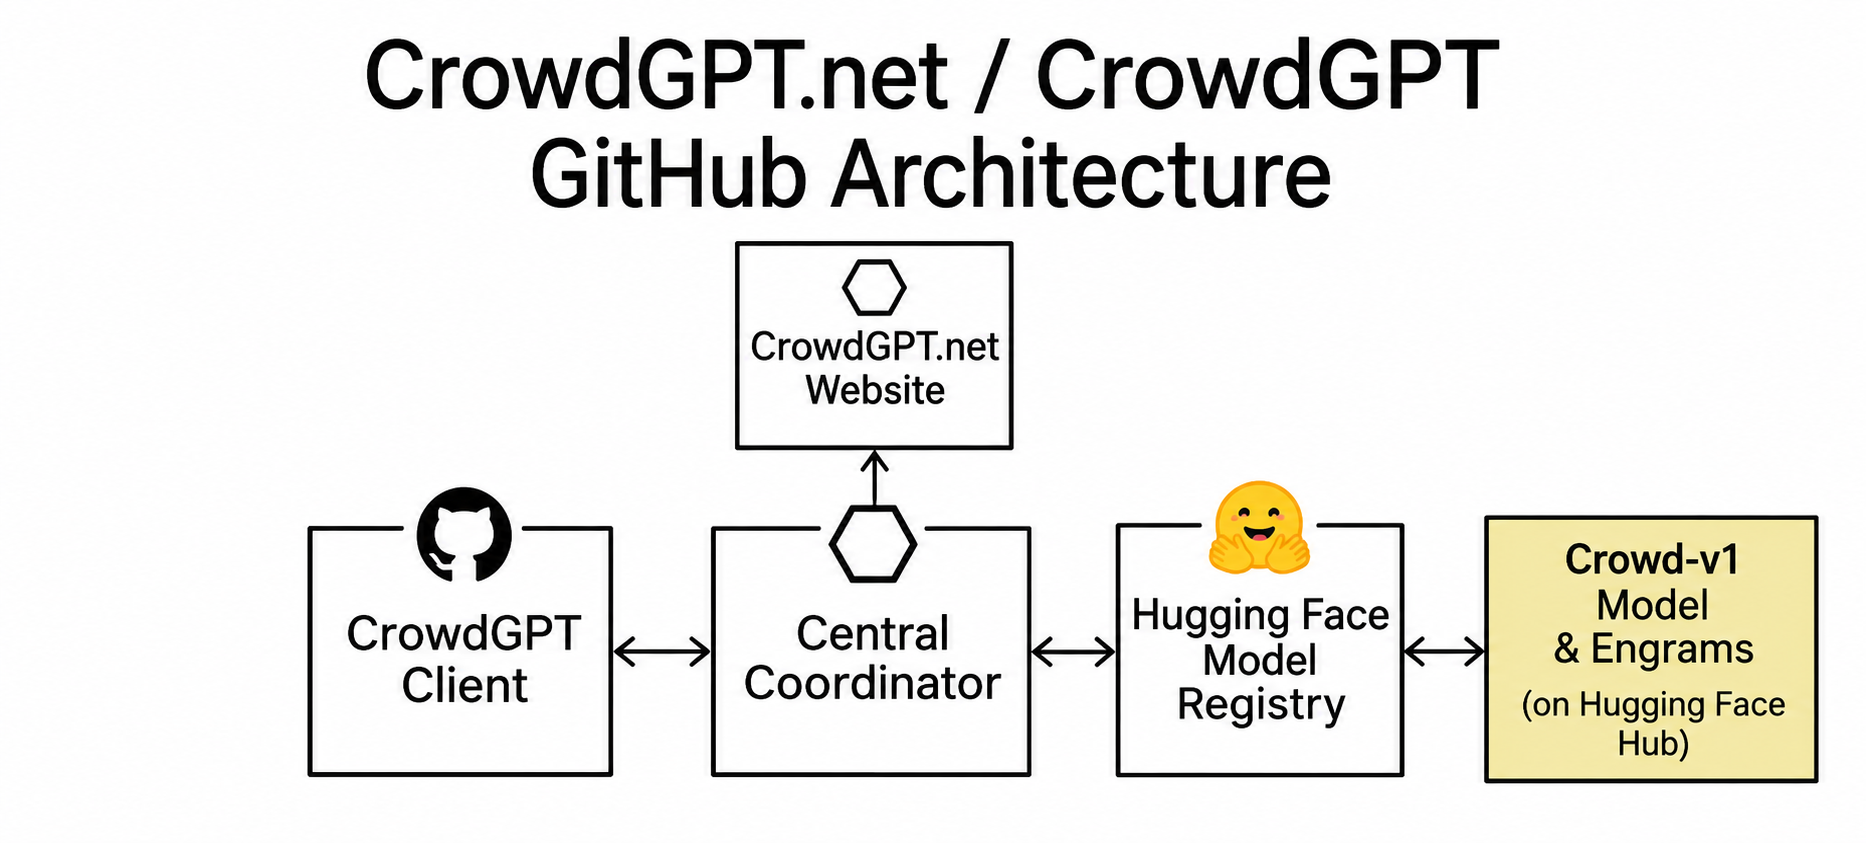
1. Task Assignment
When a device connects, the server assigns it a specific data shard (a 10MB chunk of tokenized text from the public CrowdGPT dataset) and the current global model weights. The client downloads the weights from HuggingFace and streams the data chunk locally via HTTP Range requests. The dataset is fully open and anyone can contribute to it.
2. Local Training
The app performs AI training on the local device. It calculates the path (the "delta") between the base model and the newly trained model. Nothing is ever accessed on your computer.
3. Secure Submission
The app then compresses the update, and sends it back to server for validation:
4. Aggregation
Valid updates are averaged and applied to the global AI model periodically. Model weights are automatically pushed to HuggingFace for public auditing and usage/testing.
Network Status
Real-time metrics of the CrowdGPT federated training network.
Training Pools by Hardware
See which device types are actively training vs. waiting for more pool members.
What the numbers mean
- Contributions: total model updates submitted across all contributors.
- Tokens Processed: cumulative tokens trained on by every GPU in the swarm.
- Active Clients: GPUs that have pinged the coordinator in the last 10 minutes.
- Model Loss: cross-entropy loss of the most recently aggregated update.
Stats refresh automatically every 15 seconds from the HuggingFace CDN. The global model weights are pushed to HuggingFace every 4 hours after aggregated updates complete.
Contributor Leaderboard
The top contributors powering the CrowdGPT training run. Rankings are based on total tokens processed.
| Rank | Username | Tokens | Steps | Trust Score | Submissions |
|---|---|---|---|---|---|
| Loading leaderboard... |
Submit training data
Help grow the CrowdGPT dataset. Submit text or files to the training queue. All submissions are reviewed by maintainers before being added to the public dataset.
- Plain text, documents, or any text corpus (.txt, .md, .json, .jsonl, .csv).
- Public domain, permissively licensed, or your own original work.
- No personal information, no copyrighted material you don't own, no malicious content.
The dataset is fully open and mirrored on HuggingFace. Nothing you submit here is used for training until it has been reviewed by a maintainer.
Get in Touch
Questions, bug reports, or interested in running your own coordinator? Reach out.
GitHub Issues
The best place to report bugs, request features, or discuss technical details of the federated logic.
For business inquiries, partnership opportunities, or sensitive security disclosures.
Hosting
The primary coordinator API is proudly hosted and maintained by Xevex.
Model Weights
All trained model checkpoints and configuration files are publicly available on HuggingFace.