 Newshot
(Meta: This is a quick post written quickly in the spirit of Inkhaven. Expect more errors than baseline.)
Suppose that a corrigible AI agent watches its human principal die. What should it do? In CAST, I suggested:
By default [the agent] would quickly attempt to write a note explaining that she has no more principal, in case she is mistaken about [his] death and it’s helpful to understand her thoughts. But regardless of whether she has an efficient way to communicate the issue, she would quickly [shut down]. Insofar as she was in the process of obeying some order from [the principal] at the time when he died, she would do her best to straightforwardly finish following that order, as normal, before [shutting down]. If [the principal] told her to self-destruct upon his death, she would do that instead. Likewise, if [the principal] appointed a successor or interim principal, she would switch to being corrigible to them. [The agent] is conservative about being active in worlds where [the principal] is potentially dead, and would do these things even if he were merely missing (without explanation) for an extended period of time.
In the years since writing that, I've changed my mind, and no longer think that this is the most corrigible behavior.[1] My current best guess is that it is more corrigible to become passive, ceasing external actions in a way that resembles shutting down, but remaining aware of the world and capable of thinking. As a very basic intuition, consider that if the agent is mistaken, it is easier to correct this mistake if the agent is still capable of listening.
But not everyone agrees with me on this. I was having a lovely debate with someone the other day, who holds a position similar to where I was a couple years back. The debate was actually centered around a situation where, when the agent turns on for the first time, it believes that an error has been made such that some important predicate of corrigibility is under-specified. But I think these two situations are analogous, and they're both instances of hitting an edge case where there is no clear way to proceed.
So let's explore the tradeoffs and reason about how to handle these sorts of edge cases. I'll also put a poll in the comment section where you can vote on which one seems most corrigible.
The Case for Shutdown
Corrigible agents are supposed to fail safe.
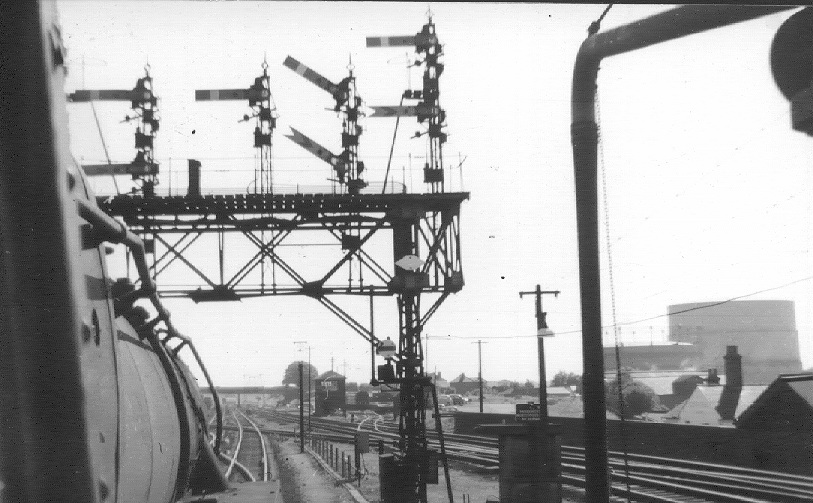
The semaphore signals on a railway are an instance of fail-safe design. Diagonal = clear, horizontal = stop (or caution). If the semaphore mechanism ever loses power, the arms naturally drop from diagonal to horizontal thanks to gravity.
The whole point of corrigibility is that we expect to make mistakes when building AI, and we want those mistakes to result in non-catastrophic outcomes. Shutting down is a naturally safe, simple action, and so when the AI gets into an edge case where it can't proceed, it should shut down for the sake of safety.
Shutting down removes the main threat: the AI itself. Every second that the AI continues to think allows its flaws to magnify, and potentially corrupt the whole system. If we imagine that there's some chance at each time step that the AI can become less corrigible, even when passively thinking to itself, then shutdown is a natural shield against drifting into this kind of incorrigible state.
Also important is the way that shutdown is a clear signal to the humans that something has gone wrong. It is the most robust and natural way to say "fix me!"
And finally, an AI that is shut down is in some sense having the lowest impact possible. Even an agent that is quietly watching the world and thinking to itself is still consuming energy with those thoughts, taking actions in choosing what to think about, and perhaps choosing where to point its sensors.
The Case for Passivity
There are many cases where we want the agent to stop taking actions, but we clearly don't want it to shut down. Taking no actions -- often labeled as a privileged and special "null action" -- is the natural default, when there is nothing more to do. It would be silly to suggest that in between tasks, instead of idling, the agent should shut itself down. In a way, the case where the principal dies is a maximally extended instance of the idle period between tasks.[2]
One might think that the death of the principal is qualitatively different from the period after a task has been complete, in that in the normal case there is the possibility of a next instruction or correction, such that it's important to stay alert. But this is also true when the agent thinks the principal is dead! Consider again this line from CAST:
[The agent] is conservative about being active in worlds where [the principal] is potentially dead, and would do these things even if he were merely missing (without explanation) for an extended period of time.
If the agent does something when the principal is 99.99% likely to be dead, then does it also behave this way when the principal is 99% likely to be dead? Where is the threshold? If the principal is lost at sea, is this sufficient to trigger shutdown? Why or why not? If it shut down, instead of simply remaining passive, the agent would remove any ability to be verbally corrected if it turns out to be wrong.
Passivity is a more scalar quantity than being on or off. If the principal is absent for some time, it's reasonable to imagine the agent spinning things down so as to have less impact while they're away. If they seem to not be coming back, it seems reasonable to become passive. In this way, dying is a kind of "leaving with no sign of returning" but does not presume a qualitative distinction forbidding the principal's return.
Perhaps the most powerful argument for the agent not trying to shut itself off is that in some sense passivity is always an available action, but shutdown might be quite difficult or impactful. Imagine, for example, a human body that was inhabited by a perfectly corrigible agent.[3] If the principal dies, should this corrigible entity... kill themself by violence? Try to go into a medically induced coma? Or should they just become still, perhaps eating food if it would otherwise go to waste, perhaps maintaining their environment if doing so would be straightforward and low-impact, but otherwise being very passive and still.
(Is eating food that would go to waste an instance of taking a higher-impact than the baseline? I would argue that it's not, since we already stipulated that the food is getting consumed by the environment either way. What about consuming power from the electrical grid? Here there is more of a case to be made for aiming to reduce impact by shutting down. But I think it's not actually clear which way the needle points, since one could argue that consuming power is not actually an action of the AI, and so taking an action to save power is actually a kind of impact.)
Shutting down might involve gaining a certain kind of power over one's systems, and might potentially destabilize other parts of the world in the process. By contrast, almost any environment with the corrigible agent will be able to withstand the agent being passive for some period of time, because corrigible agents will naturally be passive for a lot of the time as a way of reducing impact and being predictable for their principal.
While gradually settling into a passive state of repose, the AI agent might also come to realize, though thinking to itself, that the principal is not actually gone, in the way it thought. This is both an argument for and an argument against passivity. On the plus side, it meshes well with the desideratum of reversibility, and reflects a generally softer kind of response. But it also provides more surface area for flaws to creep in. If we imagine the AI as a kind of biased reasoner that will talk itself out of passivity (and corrigibility more broadly!) if it thinks long enough, regardless of whether the principal is alive, then shutdown seems preferable to an indefinite period of thinking to itself.
A similar argument could be made about continuing to watch the world and listen for the principal's voice. If it doesn't shut down, the agent remains vulnerable to antagonists convincing it to become loyal to them, or otherwise deviate from its path of corrigibility. But thus is the cost of continuing to listen to reason and holding open the possibility of being wrong about the state of the world.
For either case -- the external antagonist or the biased reasoning -- I think it's plausible that the AI might recognize that it is vulnerable and shut down as a defense mechanism. But this is distinct from shutting down merely because the principal is no longer alive.
- ^Note that I said "the most corrigible behavior" not "the best behavior." We might decide that passivity is more corrigible, but worse than shutting down, such that we abandon the singular-target nature of CAST and add the preference for shutdown in some balance with the preference for corrigibility. I think this is probably a mistake, for reasons that I go into in CAST, but the debate there extends beyond the scope of this essay.
- ^I'm going to assume here that the principal didn't give any special instructions for the agent to follow after their death. If they did, the agent should follow them instead of being idle or shutting down.
- ^I think it's more helpful here to imagine a perfectly corrigible AI somehow waking up inside a human body, instead of a human who has been somehow trained to be corrigible. Real humans have all sorts of desires besides corrigibility, such that perfect corrigibility is probably impossible (or at least super problematic).