 Newshot
Original text(via HN AI)
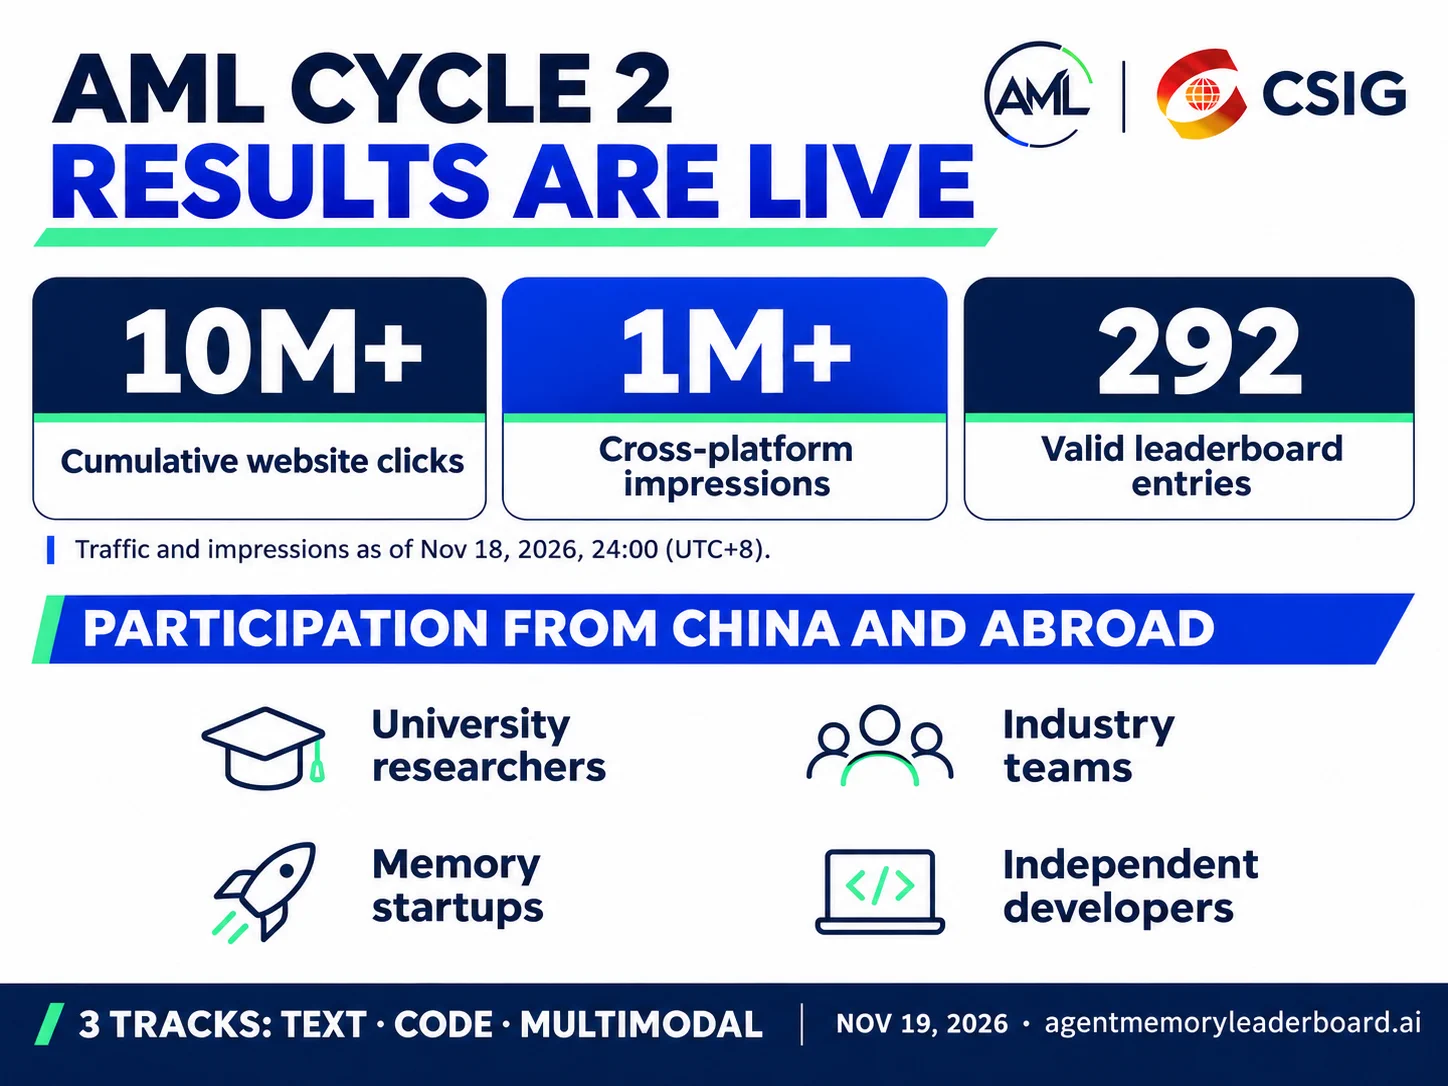
- Agent Memory Leaderboard@AgentMemoryL🏆 AML Cycle 2 results are live! 💥 • 1M+ cross-platform impressions • 10M+ cumulative website clicks • 402 task submissions • Three tracks: text, code and multimodal memory This cycle brought together teams from across the global AI community, including teams from Alibaba Cloud DMS, Shopee, OPPO, KT and OceanBase—alongside university researchers, memory startups and independent developers. Explore the full results: agentmemoryleaderboard.ai Highlights and evaluation details below 🧵2:10 PM · Nov 19, 2026·12.4KViews6


- Agent Memory Leaderboard@AgentMemoryL17hText Memory · Commercial Products 🥇 MemoraX — 69.26 points 🥈 AIDBS-Groundata — 64.32 points 🥉 Gedo Memory — 62.28 points The Top 8 also features Silent Context Engine, RetrMem, Forget, DMAI-MetaMemory and Step Memory V1.0. Explore the full rankings across all three tracks on the AML website.1Agent Memory Leaderboard@AgentMemoryL17hOpen-source leaders: • Text: Resurface — 61.22 points • Code: InsightMem — 63.33 points • Multimodal: Khipu — 43.26 points Each track features open-source, closed-source and commercial product rankings. Tasks and scoring differ across tracks, so scores should be interpreted within each track.1Agent Memory Leaderboard@AgentMemoryL17hThank you to every participating team, reviewer and community contributor who helped make AML Cycle 2 possible. We’ll share more capability breakdowns and case studies soon. What should we explore first: memory updates, coding experience reuse or multimodal evidence?
- Kawsar@Kawsar_Ai16hI'd love to see a deeper breakdown of coding experience reuse. Can an agent actually apply what worked in a previous debugging session to a new problem? That would be interesting to explore.
