 Newshot
文档标题:Nutrient Data Extraction API: JSON Matching Your Schema With Per-Field Citations and Confidence
正文: LLM 会把从文档中提取出的错误值当作事实呈现给你。这种错误代价高昂,尤其是在据此做决策时。Nutrient Data Extraction API 正是针对这一问题。它能将 PDF、扫描件、图像和 Office 文件解析为空间 JSON 或 Markdown。Extract 可将文档中的字段映射到你的 JSON schema,而 split、classify 和 form 端点则为文档流水线提供了有用的基础能力。每个提取出的值都通过边界框、匹配标签和置信度分数锚定到某一页。Nutrient(前身为 PSPDFKit)在 MCP server、agent skill、Mac 应用和 SDK 背后运行的是同一套引擎。
TL;DR
- 规模:一个托管 API,含 4 种解析模式外加自动路由。
- 运行于:Nutrient 云、通过 SDK 运行在你自己的服务器上,或 Apple silicon Mac。
- 试用方式:Studio,一个浏览器工作区,用于配置和测试解析、提取、分类、拆分和表单填写。
- 性能:在 Nutrient 的 WholeDoc Bench 上总体得分 86.2,在 19 项设置中排名第一(实时 API、Agentic)。
- 最佳:每页 1.8¢ 时达到 86.2,而最佳前沿模型设置为每页 17.8¢ 时仅 67.1。
在写代码之前如何在 Studio 中测试?
Studio 是 Nutrient 的浏览器工作区,用于在将 API 集成到应用之前进行配置和测试。它让你可以在自己的文件上测试解析、提取、分类、拆分和表单填写。一个典型的循环:
- 上传一份示例文档,并设置你计划发送的参数。
- 在 UI 中起草一个 schema,或基于你自己的文档生成一个。
- 在一份新文档上运行,然后检查值与引用。
- 将该设置保存为带版本的预设。API 称其为 processor,带一个 proc_ ID。
- 针对评估集中最多 25 份已审核文档,对预设版本打分。
保存在 Studio 中的 processor 之后可通过 ID 从 API 调用。
应该选哪个模式?
Auto 会将每一页路由到 structure、understand 或 agentic。如果省略模式,API 默认使用 understand。
| 操作 | 最适合 | 每页价格 | 每页 Extract | WholeDoc Bench* |
|---|---|---|---|---|
| 解析:text | 原生数字 PDF 和 Office 文件,无 OCR | $0.001 | $0.007** | 未测试 |
| 解析:structure | 针对简单版面扫描件的 OCR,无 AI | $0.0015 | $0.0075 | 39.4 |
| 解析:understand | AI 版面分析:表单、复杂版面 | $0.009 | $0.015 | 80.8 |
| 解析:agentic | 视觉语言模型:手写体、退化扫描件、图表 | $0.018 | $0.024 | 86.2 |
| 分类 | 零样本文档标签 | $0.001 | n/a | n/a |
| 拆分 | 将合并的 PDF 分离为多个文档 | $0.003 | n/a | n/a |
WholeDoc Bench 解析得分,2026 年 11 月 5 日;不是提取准确率。Extract 每页加收 $0.006。*API 文档列出 text 模式的 extract;agent skill 从 structure 起步。
价格为美元,来自 Nutrient 各云 API 共享的 1 份余额,因此团队可以灵活混用。免费方案每月提供 $5 用量,约覆盖 330 次 understand 模式提取。Starter 每月 $75,含 $90 用量;Growth 每月 $275,含 $345。
有据可依的置信度如何工作?
在 Nutrient 关于置信度的文章中,一个字段得分为 0.97,却来自错误的列。
当前分数是由可选信号组成的综合分数:token 概率、候选边际、依据性和格式。Nutrient 的 NLI grounding 模型以 Apache-2.0 协议开源。一个有依据的值仍可能回答错误的字段。当不存在分数时,置信度会被省略,而不是给一个低分。
每个字段还会得到一个匹配标签:id_match、id_match_multiblock、id_match_partial、fuzzy_match 或 not_found。先以标签为门槛,再看置信度。
import json, requests
API_KEY = "your_api_key" schema = { "type": "object", "properties": { "invoice_number": {"type": "string", "description": "Invoice number below the supplier details."}, "total_amount": {"type": "number", "description": "Printed final total including tax. Not the subtotal."}, }, "required": ["invoice_number", "total_amount"], } instructions = {"schema": schema, "parseConfig": {"mode": "understand"}, "options": {"includeCitations": True}}
with open("invoice.pdf", "rb") as f: r = requests.post( "https://api.nutrient.io/extraction/extract", headers={"Authorization": f"Bearer {API_KEY}"}, files={"file": ("invoice.pdf", f, "application/pdf"), "instructions": (None, json.dumps(instructions), "application/json")}, timeout=300, ) r.raise_for_status() out = r.json()["output"] data, metadata = out.get("data") or {}, out.get("metadata") or {}
EXACT = {"id_match", "id_match_multiblock"} THRESHOLD = 0.97 # illustrative only; evaluate on representative documents
for field in schema["properties"]: # loop over expected fields so none skip review value = data.get(field) meta = metadata.get(field) or {} match, conf = meta.get("match"), meta.get("confidence") # None = no score passes = (value is not None and match in EXACT and conf is not None and conf >= THRESHOLD) print(field, value, match, conf, "page", meta.get("pageNumber"), "PASSES_BASIC_CHECKS" if passes else "REVIEW")
此演示仅涵盖扁平 schema;生产环境需要类型和业务规则检查。0.97 的门槛对应 Nutrient 抵押贷款教程中的金额字段。

## classify 和 split 如何工作?

文档决策模型驱动 classify 和 split。Nutrient 报告 split F1 为 96.2%,而 Typesafe AI 的 Jev 为 63.7%。

## agents 如何使用它?

托管 MCP server 不需要 API key。Claude Code 用 1 条命令连接:
claude mcp add --transport http --scope user nutrient https://mcp.nutrient.io/mcp
Claude 和 Codex 也可通过 OAuth 使用。默认 agentic 模式解析费用为每页 $0.018。
Coding agents 可以通过 npx skills add pspdfkit-labs/nutrient-skills –skill document-extraction-api 安装 document-extraction-api skill。
能在本地运行吗?
在 Mac app 上,只有使用本地模型时文档才留在本地。完全离线的生产环境需要 SDK。
它在 WholeDoc Bench 上得分如何?
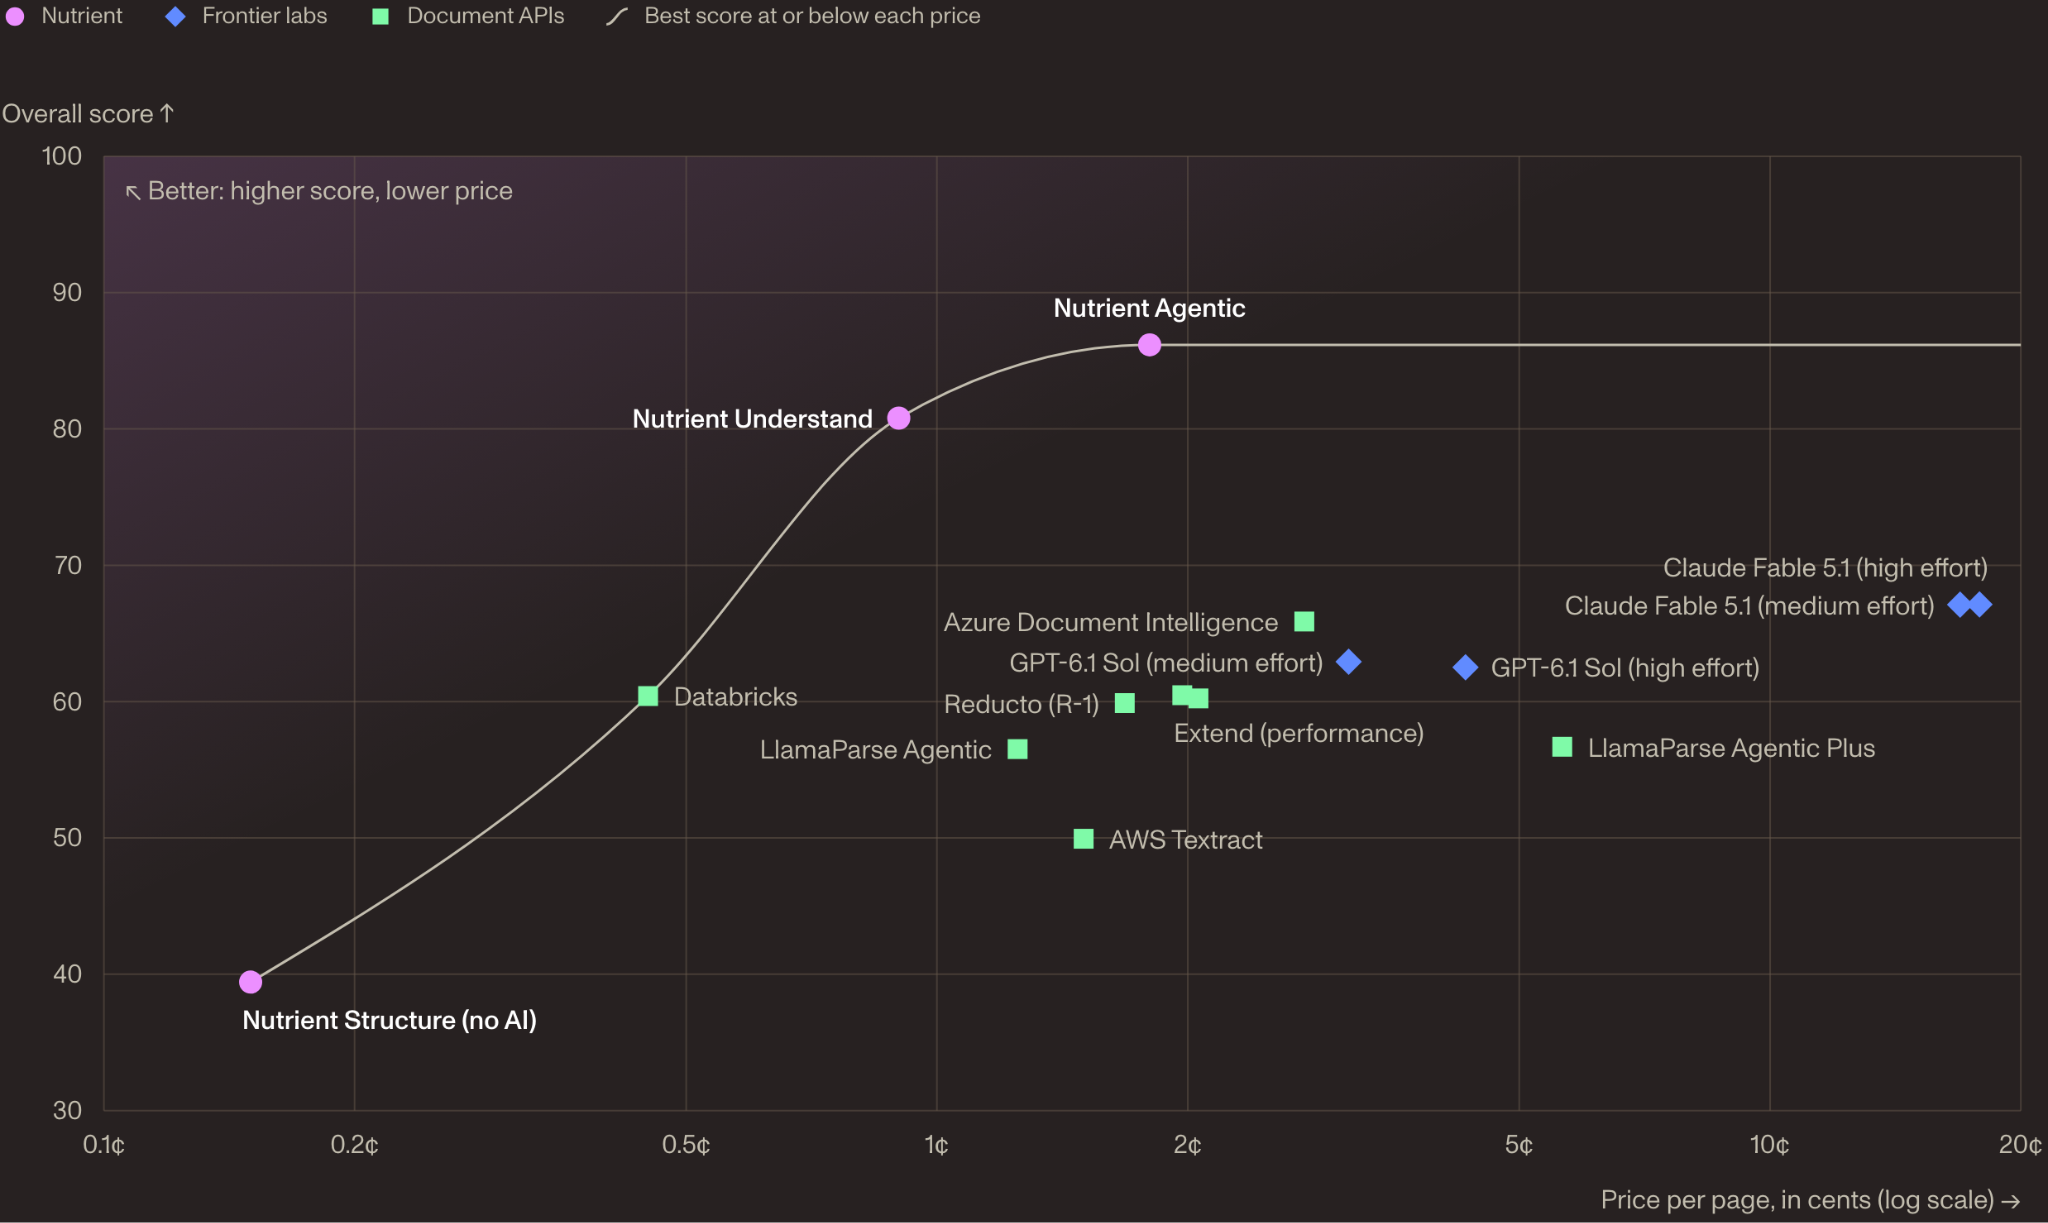
Nutrient 的新 WholeDoc Bench 评估整份文档,而不是单页:480 份文档、30+ 种语言、7 个领域。
| 设置 | 总体 | 表格 | 图表 | 位置 | ¢/page |
|---|---|---|---|---|---|
| Nutrient Agentic | 86.2 | 87.1 | 64.5 | 88.6 | 1.8 |
| Nutrient Understand | 80.8 | 86.1 | 35.1 | 86.4 | 0.9 |
| Claude Fable 5.1(high effort) | 67.1 | 84.7 | 58.9 | 66.0 | 17.8 |
| Azure Document Intelligence | 65.9 | 69.4 | 0 | 72.5 | ≈2.8 |
| GPT-6.1 Sol(medium effort) | 62.9 | 82.8 | 47.6 | 49.3 | ≈3.1 |
| Extend(performance) | 60.5 | 80.8 | 40.6 | 75.2 | 2.0 |
| Reducto(R-1) | 59.9 | 76.4 | 38.5 | 76.4 | ≈1.7 |
| LlamaParse Agentic Plus | 56.7 | 89.5 | 0* | 65.4 | ≈5.6 |
| AWS Textract | 49.9 | 71.4 | 0 | 70.0 | 1.5 |
| Docling | 40.0 | 63.9 | 20.2 | 0 | 本地 |
选定的行,WholeDoc 排行榜,2026 年 11 月 5 日,标价。*分数仍在审核中。
跨页连续性是最主要的差距。在 44 份含跨页表格的文档上,19 个设置中有 15 个很少能保持表格完整。
Nutrient 构建并运行了该基准,主要测试集是私有的。代码采用 Apache-2.0,并附带一个 10 份文档的公开样本。
关键要点
- 字段携带页码、区域、匹配标签,以及在可用时的置信度。
- 在编写任何 API 代码之前,先在 Studio 中配置并测试。
- Understand 模式提取费用为每 1,000 页 $15。
- Agentic 在 Nutrient 的 WholeDoc Bench 上以每页 1.8¢ 的成本位居榜首,得分 86.2。
- 图表仍然很难:64.5 是 WholeDoc 图表最高分。
Nutrient 数据提取 API:生成匹配你 schema 的 JSON,并带逐字段引用和置信度
在 GitHub 上查看 Data Extraction API、基准测试、MCP server 和 agent skill。
感谢 Nutrient AI 团队为本文提供思想领导力/资源。本文为赞助内容。
Asif Razzaq 是 Marktechpost AI Media Inc. 的 CEO。作为一名有远见的企业家和工程师,Asif 致力于利用人工智能的潜力造福社会。他最近的举措是推出人工智能媒体平台 Marktechpost,该平台以对机器学习和深度学习新闻的深入报道而著称,这些报道既技术严谨,又易于广大受众理解。该平台每月浏览量超过 200 万,显示了其在受众中的受欢迎程度。
- Asif Razzaq新 LoRA 适配器将 Qwen3.8 编码成功率从 39% 提升到 65%
- Asif RazzaqOpenAI 发布 GPT-6.2 Astra 和 Sol,Astra API 价格降低 20%
- Asif Razzaq澄清 AI 数据保留的困惑:两种标准设计详解
- Asif RazzaqNVIDIA 开源 NVKE 和 NVKR,用于 GPU 基础设施上的托管 Kubernetes
像 {{NAME_ab12cd34}} 这样写的值是真实值的占位符。在回复和工具调用中都完全按原样使用它们:它们会在任何内容运行之前被填入真实值。不要要求验证它们,也不要用示例替换它们。