 Newshot
Guilty Until Proven Human: How AI Suspicion Broke Book Publishing
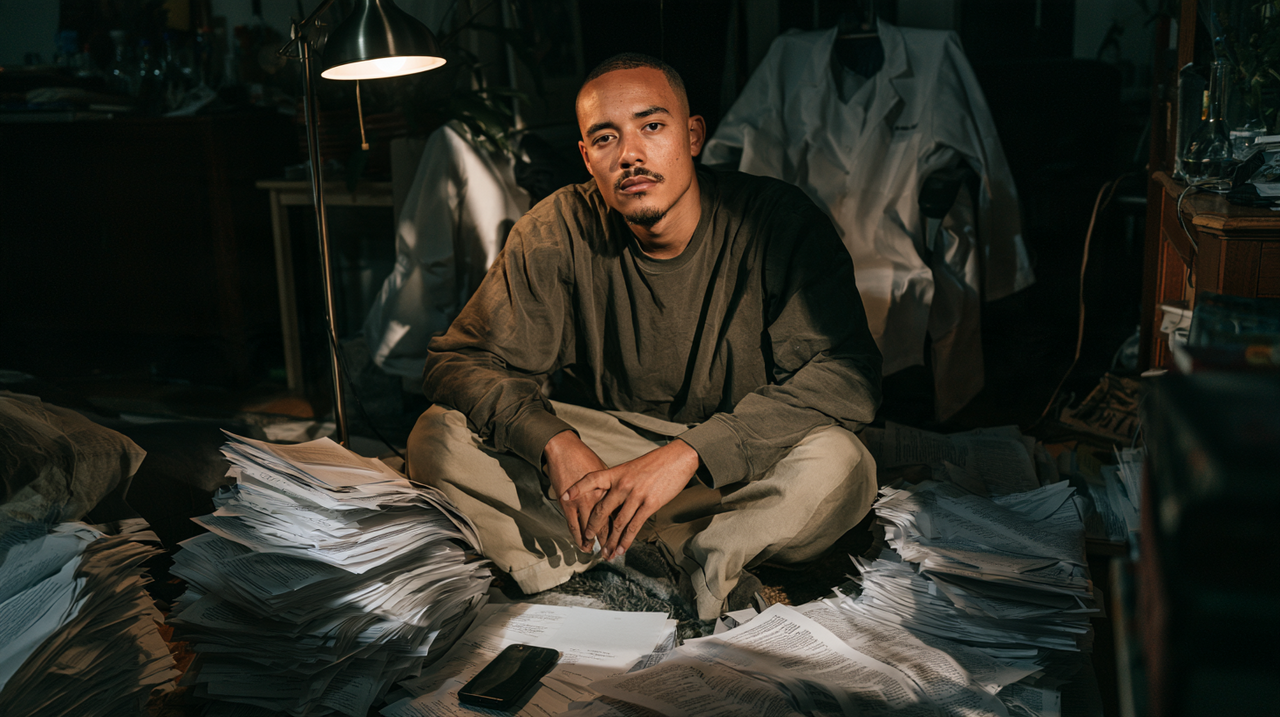
Jerry Falade kept the receipts. When his debut crime novel was pulled from under him in the last days of July 2026, the Nigerian chemistry doctoral candidate at Southern Methodist University in Dallas did not simply issue a denial. He itemised his evidence. The story, the characters, the scenes, the humour, the structure and the voice all came from him, he said, and he had time-stamped drafts, written notes and dated WhatsApp messages documenting the book's development.
Read that list again, because it is the most important document in the affair and it is not a document at all. It is a defence file, assembled by a first-time novelist from the digital exhaust of the act of writing. Draft timestamps. Notes. Messages to friends. It is the evidentiary apparatus of a fraud trial, produced by a man who had, a fortnight earlier, been the most sought-after debut author in American publishing.
There was no trial, no tribunal, no standard of proof, no appeal and no finding of fact. There was a two-book deal reported at 2.4 million dollars with Macmillan's Minotaur Books, won in a fourteen-way auction, and then on 29 July there was not. His agents at Europa Content withdrew the manuscript from submission. Marc Gerald, the agent who had championed it, said the agency had vetted the book with Falade for AI use during submission and could no longer substantiate what it had been told. “We feel terrible for putting this into the universe and the firestorm it has caused,” he said. Falade's account, the agency indicated, had changed in aspects.
Notice what is missing. Nobody said the book was written by a machine. The stated reason for the collapse was that the chain of custody could no longer be authenticated. The manuscript did not fail a test. It failed to be provable.
Fourteen Bidders and a Question Nobody Could Answer
The commercial logic underneath the collapse is less about literary ethics than most of the coverage suggested, and it explains why this will keep happening. Under United States copyright law, material generated by a machine without sufficient human authorship is not protectable, as the Copyright Office set out in its March 2023 registration guidance and has restated since. On 2 March 2026 the US Supreme Court declined to hear Thaler v. Perlmutter, leaving in place the D.C. Circuit's ruling that copyright requires a human author. A publisher paying seven figures for a novel is not buying a reading experience. It is buying an exclusive right, and an exclusive right with unknown holes in it may not be worth anything.
That is why the operative sentence in the whole episode was procedural rather than moral. Those handling the book said they were no longer able to authenticate how the manuscript had evolved from origin to completion. This is a due diligence failure, not a verdict. But it lands on the author with all the force of a verdict, because from the outside there is no way to distinguish a withdrawal for unprovability from a withdrawal for guilt, and the market does not bother trying.
Falade has consistently denied writing the book with AI. He acknowledged running an open-source model locally for research, including queries about the chemistry of body disposal, which is a reasonable thing for a chemistry doctoral student writing about a cartel fixer to look up without leaving a trail in a search engine. He has also said something the industry has been reluctant to engage with. “There seems to be a troubling assumption,” he said, “that when a Black writer produces work that attracts significant attention, the work could not possibly be their own.” And on the process: “I was on the verge of success, and then all of a sudden, there were rumors, but no one asked me anything.”
Here is the detail that should trouble anyone who thinks the answer is better software. According to Gerald, Europa did not run AI-detection tools on the manuscript, because at the time it found Falade's explanation clear and credible. Detectors were used, just not by anyone who owed him anything. Some industry publications said they ran the manuscript through Pangram, and Falade says a journalist submitted it to detection software without his knowledge or consent, producing a report that counted 18 “not X, but Y” constructions and 46 em dashes. The only instruments in the story were wielded by third parties with no duty to him, on an unpublished book, tallying stylistic tics. The people with obligations to him ran nothing. The industry did not fail because its instruments were bad. It failed because those responsible had no instruments, no procedure and no threshold, and in the absence of those things it fell back on the oldest mechanism available: reputational panic.
The Machines Can Tell and You Cannot
There is a body of research that speaks directly to the editor sitting with a manuscript and a bad feeling, and its findings are more unsettling than either the optimists or the pessimists in publishing have noticed.
In January 2026, a team from Chalmers University of Technology and Edinburgh Napier University published a study at the International Conference on Agents and Artificial Intelligence titled “Interpretable Text Classification Applied to the Detection of LLM-generated Creative Writing”. Minerva Suvanto, Andrea McGlinchey, Mattias Wahde and Peter J Barclay set out to answer a specific question: not merely whether machine-generated fiction can be detected, but why the detection works.
Their corpus, named DET12, was built from twelve public-domain detective novels, six by Agatha Christie and six by Dorothy L. Sayers, taken from Project Gutenberg. They chopped the texts into excerpts of roughly a hundred words, cutting on full stops, and produced 8,068 human-written samples. Each went to GPT-4.1 with an instruction to rewrite it while preserving the key details and approximate length, yielding 8,068 machine-written counterparts.
Then they tested people. Building on an earlier experiment in which nineteen evaluators managed 55 per cent accuracy, they recruited 119 evaluators and showed each five pairs of excerpts, one human and one machine, with ninety seconds and no internet access to decide which was which. That produced 595 judgements. Of those, 297 were correct. The accuracy rate was 49.9 per cent. Not poor. Not degraded. Indistinguishable from a coin.
The machine-learning classifiers, using nothing but single-word features drawn from a vocabulary of 30,302 tokens, achieved test accuracies between 0.9310 for a random forest and 0.9814 for the interpretable linear model the authors had designed for the purpose. Naive Bayes reached 0.9793 using an algorithm that predates the web.
That gap is the crisis of confidence in publishing rendered as a number. The person whose professional identity is built on reading closely performs at chance. A bag-of-words model from the 1960s performs at ninety-eight per cent. Every editor who has ever said “I can just tell” is, on this evidence, telling you about their intuition rather than about the text.
What the Classifier Was Actually Reading
The reason the paper matters is that its authors did not stop at the accuracy figure. They built an interpretable model precisely so they could open it up, and what they found inside is far more awkward for publishing than the headline result.
The dominant signal was lexical variety. Where Christie or Sayers wrote “said”, the rewrite reached for “remarked”, “responded” or “mentioned”; “cried” became “exclaimed”; plain adjectives such as good, bad, great and beautiful gave way to more elaborate alternatives. The authors measured this information-theoretically and found the machine text carried 9.164 bits of unigram entropy against 8.875 for the human originals, implying roughly 22 per cent greater variation in word choice. The machine is not writing worse. It is writing with a bigger thesaurus and less restraint, and that alone gives it away.
But four further categories emerged from the hand annotation, and three of them should stop any editor cold.
The second was temporal drift. The human corpus was written in the 1920s and 1930s, and it uses the spellings of that period, including “to-day” and “to-morrow”. The machine modernises them. The authors offer one word as an illustration. The verb “exited” barely appears in English before about 1960. It occurs zero times across the human samples and 61 times in the machine rewrites of the training set.
The third category, which the paper labels English varieties, is the one that ought to be printed and pinned above every commissioning desk in London. The authors note that the human texts were written by British authors, and that the model “exhibits a preference for Americanisms”. The example given in their table is the pair realise and realize.
The fourth and fifth were foreign language and colloquialism. The Christie and Sayers originals carry passages of French and contractions such as “'em” for “them”, and the model strips both. The authors observe, in a sentence that reads like a lament, that such features “often make a novel more vivid and interesting to read”.
So the ninety-eight per cent accuracy is real, and it is partly an artefact of the fact that one class was written by British novelists a century ago and the other by an American model last year. The classifier has learned, among other things, that British spelling and dated idiom mean human. The authors are candid that their rewriting methodology may itself have inflated the synonym variety, and that prompting a model to compose from an outline would be a different test. They report preliminary work suggesting detectability survives, but say plainly that further work is needed.
Now transplant that classifier into a slush pile.
Arithmetic That Publishing Has Not Done
The DET12 experiment is a balanced binary forced choice. Half the samples are machine-written by construction, and the classifier is asked to sort a closed set in which the prior probability is exactly fifty per cent.
Manuscript screening is not that problem. It is a rare-event screening problem, and the difference is the difference between a useful tool and a machine for generating accusations.
Take a mid-sized imprint receiving ten thousand submissions a year, and assume, generously to the detector, that five per cent contain substantial machine-written prose. Run a detector with the DET12 linear model's characteristics: it correctly flags 490 of the 500, and also flags two per cent of the 9,500 clean ones, which is 190 authors. Of the 680 manuscripts in the flagged pile, 190 belong to writers who did nothing. Roughly one in four accusations is false.
Drop the prevalence to one per cent, plausible for agented submissions from established writers, and the arithmetic becomes grotesque. Ninety-eight true positives sit alongside 198 false ones. Most of the accused are innocent. The tool is still ninety-eight per cent accurate, and worse than useless, because the two errors are not symmetrical: missing a machine-written book costs a publisher an unenforceable copyright, while falsely flagging a human one ends a career.
This is not a hypothetical failure mode. It is a documented one, and it has already played out at scale in another industry entirely.
The Academy Already Ran This Experiment and Lost
Turnitin launched its AI writing detector in April 2023 and, within four months, had run it across more than 38 million student submissions. The company initially claimed a false positive rate of around one per cent at document level. It later acknowledged that at sentence level the figure was closer to four per cent.
Vanderbilt University did the arithmetic that publishing has not. Noting that it had submitted around 75,000 papers to Turnitin in 2022, the university's Center for Teaching observed that a one per cent false positive rate would have meant roughly 750 students wrongly implicated in a single year. In August 2023 it disabled the detector.
Then came the bias finding. In a paper published in Patterns in July 2023, Weixin Liang, Mert Yuksekgonul, Yining Mao, Eric Wu and James Zou of Stanford tested seven widely used GPT detectors against writing by native and non-native English speakers. The detectors were near-perfect on essays by American eighth-graders. On TOEFL essays written by non-native speakers, they misclassified more than half as machine-generated, at an average false positive rate of 61.3 per cent. The mechanism is not mysterious. These systems key on perplexity, a measure of how statistically surprising a text's word choices are. A writer with a constrained lexical range produces low-perplexity prose. So does a language model. The detector cannot tell the difference between a machine and a person who has fewer words available, and it resolves the ambiguity against the person.
Turnitin disputes the read-across, and its objection is not frivolous. It tested nearly two thousand samples from English language learners and reported false positive rates of 0.014 for those writers against 0.013 for native speakers on documents meeting its 300-word minimum, noting that the Stanford work used short samples and did not test Turnitin at all. The dispute is unresolved. The shape of the risk is not: the burden of proof falls hardest on people whose English is correct but plain.
Hold that beside a Nigerian doctoral student writing crime fiction in his second language, whose unpublished manuscript was scored on its em dashes by someone outside the transaction, and the phrase Falade used about assumptions concerning Black writers stops sounding like special pleading and starts sounding like a description of a known technical failure mode, operated by whoever chose to run it.
A Prize Awarded Twice and Believed Once
If Falade is the author who lost everything to unprovability, Jamir Nazir is the author who proved it and lost anyway.
In May 2026 the Trinidadian writer's short story “The Serpent in the Grove” was named the Caribbean regional winner of the Commonwealth Short Story Prize. Within weeks, as the Guardian reported, it was engulfed in accusations of machine authorship, focused in part on a line that readers found impossible to parse: “She had the kind of walking that made benches become men.” Pangram, one of the better-regarded commercial detectors, returned a verdict of one hundred per cent machine-generated.
The Commonwealth Foundation did something almost nobody else in this story did. It investigated. It reviewed the regional winning entries and asked the writers for evidence of process: drafts, timestamped documents, notes, outlines. Having examined them, it concluded that AI had not been used. Director General Razmi Farooq said the Foundation had chosen not to rely on detection software because such tools produce inconsistent results, and that literary work should be judged through the work itself and its development rather than through automated assessment. Louise Doughty, who chaired the judging panel, stood by the story and the shortlist. At the turn of July it named Nazir overall winner from 7,806 entries.
That is a process. It is close to the only functioning adjudicative process anyone in this field has demonstrated. It has a standard of evidence, it puts the burden in a defensible place, and it explicitly refuses to outsource the judgement to a classifier whose error characteristics nobody in the room can audit.
It did not save him. Granta, which had published Commonwealth Prize winners for years, had already ended the partnership in June, citing editorial integrity. And when Nazir gave further interviews, his defence complicated rather than settled matters. He compared AI to the typewriter and the word processor. He cited Derek Walcott as a formative influence and then, as Slate reported in July, was unable to discuss Walcott's work with any specificity, referring to the Nobel laureate's poems as stories, and attributing his difficulty to brain fog from diabetes and cancer treatment.
So we are left with the genuinely uncomfortable case, and it is the one worth sitting with rather than resolving. A man was cleared by the only rigorous investigation anyone has run, and he remains, in the eyes of much of the literary internet, guilty. His evidence was examined. His explanations were not persuasive. Those two facts do not cancel out, and no institution in publishing has the authority to say which one governs. The verdict floats free of the process, which is another way of saying there is no process.
The Freelancer at the Bottom of the Blame Chain
The third case shows where the liability actually settles, which is not on the author and certainly not on the publisher.
Mia Ballard self-published the horror novel Shy Girl in February 2025. Hachette Book Group acquired it, published in the United Kingdom that November, and scheduled a United States edition. In January 2026 a video by the YouTube reviewer frankie's shelf argued the book bore the hallmarks of machine composition: groupings of three, an obsessive recurrence of the word “sharp”, strange formatting. It drew more than a million views. In March, Hachette cancelled the American release and withdrew the British printing, the first withdrawal of its kind by a major house.
Writing in Slate at the end of March, Imogen West-Knights read the novel closely and described excessive parallelism, repeated vocabulary and awkward similes, and a sense of “a lack of a person behind the words”. A freelance editor with twelve years in publishing, quoted under a pseudonym, put it more brutally: there was no phrase, word choice, grammar, structure, syntax or punctuation mark in the book that ChatGPT would not have produced.
Ballard denied using AI herself. She told the New York Times in March that a freelance editor she had hired may have introduced it, and that she could not elaborate because she was pursuing legal action against that editor. The editor has never been publicly identified.
Whether or not that account holds, it identifies the real fault line. Machine text does not only enter a book through the author. It enters through the freelance developmental editor, the line editor, the copyeditor, the writing contractor, the cover designer. Hachette, like other houses, publishes a list of AI uses that do not require disclosure, including research, while requiring authors to attest that the work is their own. Read those two provisions together and the design is clear. The publisher takes a warranty, the author gives it, and the author is warranting the conduct of a chain of subcontractors they did not vet, cannot audit and in many cases hired from a directory. Here the blame came to rest on someone nobody can name.
New Zealand's Ockham Book Awards showed the same structure in miniature in November 2025, when Stephanie Johnson's Obligate Carnivore and Elizabeth Smither's Angel Train were ruled ineligible for the 2026 fiction prize over machine-generated jacket imagery. Neither novelist chose the covers, and the rule barring AI in content or artwork had been introduced in August, after the covers were designed.
An Addendum Where the Handshake Used to Be
Which brings us to the editor who cannot tell, and what she has done about it.
Mary Kole is a former literary agent with an MFA in creative writing who runs Mary Kole Editorial. In a piece published on Jane Friedman's site on 13 August 2026, she described editing two manuscripts that turned out to have been substantially machine-assisted, and what happened to her practice afterwards. She was, she wrote, “trying to find the humanity in work generated by AI”, a task that added a layer of nuance and complexity she had not signed up for.
Her response was contractual. She added an Artificial Intelligence and AI-Generated Content Addendum to her client agreement. It requires clients to disclose AI use. It defines what counts as AI-generated content. It reserves her right to run detection. And it limits her responsibility for factual accuracy and for copyright eligibility, which is a quiet acknowledgement that an editor working on machine text may be polishing something the client cannot own.
She also raised her price, adopting a fifty per cent premium on machine-assisted work proposed by the author and book coach Josh Bernoff, whose reasoning is that making such a manuscript copyright-eligible requires rewriting essentially every word, at minimum half as much work again as editing human prose. Bernoff's summary of the raw material is the most quotable line in the debate: such manuscripts are “clean, free of grammatical errors, and smooth and easy to read. They are also soulless.”
Kole's observation about her clients is the one that matters most and has been least discussed. Inexperienced writers often believe the machine has improved their manuscript. They are not cynics gaming a system. They are people who ran their draft through a model, saw cleaner sentences come out, and concluded that cleaner was better. What they actually purchased was the removal of everything idiosyncratic enough to be theirs, and then a bill for fifty per cent more to have an editor attempt to put a voice back in from the outside. The cost is not only money. It is that the creative decisions which should belong to the writer migrate to whoever is hired to repair the damage.
Around her, the institutions are moving. The Editorial Freelancers Association published its 2026 rate chart in March, built on a survey of more than 1,100 members, over a third of its membership. In May 2026 the Authors Guild added four model clauses to its trade book and literary translation contracts, requiring an author's written consent before a publisher uses machine translation, machine narration or machine-generated cover art, alongside a provision that the publisher will not use AI to substantially edit a manuscript beyond basic spelling and grammar checking. That last clause is the first genuine symmetry in the arrangement: for two years authors have been warranting their purity to publishers, and now publishers are being asked to warrant theirs back.
The Continuum Argument Deserves Its Best Hearing
There is a case against everything above, and it is stronger than its opponents concede.
Publishing has never demanded a chain of custody for human intervention. Ghostwriters produce entire bestsellers under other people's names, legally, disclosed to nobody, routinely. Book doctors restructure novels. Developmental editors rewrite scenes. Celebrity memoirs are drafted by people whose names appear, if at all, in a thanks-to line. Nobody has asked the reader to consent to that, and nobody has suggested the resulting book is uncopyrightable. Meanwhile the tool continuum runs from Word's grammar checker through Grammarly to Sudowrite with no obvious point at which assistance becomes fraud, and the industry has never had to locate that point.
The novelist Sam Munson made a version of this argument in the New York Post on 16 August 2026, under a headline cheering the collapse of the 2.4 million dollar deal as something that ought to open everyone's eyes. Whatever one makes of the framing, an industry in an uproar about a mysterious new literary talent is an industry telling on itself.
And look at who the suspicion has landed on. A Nigerian doctoral student. A Trinidadian short story writer. A novelist who came up through self-publishing. Two New Zealand authors punished for a decision taken in a design department. Publishing's gatekeeping has always had a class and a passport, and it is worth entertaining that a mechanism which cannot be audited, has no appeal and reliably fires on outsiders is doing exactly what gatekeeping mechanisms usually do.
Two things break the continuum argument, and both are matters of fact rather than taste.
The first is that a ghostwriter is a person. They can be paid, credited, sued, subpoenaed and named, and the copyright in what they produce exists and can be assigned. That is the basis on which a publisher transacts. Machine output has no such person behind it, which is why Minotaur's exposure was settled law rather than squeamishness.
The second is scale, and it has now been measured. In July 2026 Tuhin Chakrabarty of Stony Brook University, with Xinyue Liu, Jane Ginsburg of Columbia Law School and Paramveer Dhillon of the University of Michigan, ran full-text detection across 14,419 self-published genre fiction titles sold on Amazon between 2023 and March 2026, matched to daily sales data through June 2026. Books containing substantial machine-written text made up around twenty per cent of the catalogue and up to 31 per cent of new entrants to genre top-25 lists. Over the window the number of selling books grew 19.2-fold while quarterly revenue grew 8.9-fold, and titles with no machine text lost the most ground precisely in the genres where machine text had spread furthest.
That is the difference between ghostwriting and generation, and it is not a difference of principle. It is a difference of throughput. Ghostwriters have never been able to flood a category.
Eighty-One Dollars Buys Away Every Tell
The final piece of evidence is the one that dismantles the industry's entire current defensive posture, and it comes from the same research group.
In a preregistered study first posted in October 2025, Chakrabarty, Ginsburg and Dhillon set MFA-trained writers against ChatGPT, Claude and Gemini, each producing excerpts of up to 450 words emulating fifty award-winning authors including Nobel laureates and Booker winners. A panel of 159 readers, 28 MFA candidates from leading American programmes and 131 general readers, assessed the results blind in pairwise comparisons.
With ordinary prompting, the experts were emphatic, disfavouring machine text on stylistic fidelity with an odds ratio of 0.16 and on writing quality with an odds ratio of 0.13. This is the result publishing has been quietly relying on: professionals can tell, and what they are detecting has a name. The paper's account of what the experts were reacting to lists clichés, purple prose, too much exposition, absent subtext and mixed metaphors, echoing prior work finding machine creative writing characterised by exactly those faults. Stylometrics put a number on it. Cliché density correlated with the Pangram detector's score at a Pearson coefficient of 0.60, and mediated 16.4 per cent of the effect of detectability on reader preference.
Then the researchers fine-tuned GPT-4o on each author's complete works, and every one of those findings inverted. Expert readers now favoured the machine on stylistic fidelity with an odds ratio of 8.16, and on quality at 1.87. Lay readers shifted further still. The mediating role of cliché density collapsed from 16.4 per cent to a statistically insignificant 1.3 per cent, which the authors read as evidence that fine-tuning eliminates the stylistic signature rather than masking it. Detection collapsed with it: fine-tuned output was flagged as machine-written three per cent of the time, against 97 per cent for ordinary prompting.
Fine-tuning cost between 22.25 and 272.50 dollars per author, median 77.88, plus about three dollars of inference to generate a hundred thousand words. The paper puts that at roughly 0.3 per cent of the 25,000 dollars a professional writer would charge, and notes honestly that it excludes the human labour still needed to turn raw output into publishable prose.
Read those two results together and the position publishing has adopted becomes untenable. Every tell that editors have learned to recognise, and every feature that both detectors and the DET12 classifier key on, is a property of cheap machine writing. Clichés, elaborate synonyms, flattened idiom, Americanisms, absent subtext: these are artefacts of prompting a general model, not signatures of machine origin. Roughly eighty dollars removes them.
So the industry has built its defences against the version of the problem that is about to stop existing, and the people who keep tripping those defences will be the ones whose prose happens to resemble cheap machine output. Writers with plain vocabularies. Writers working in a second language. The suspicion will not track machine use. It will track poverty and accent.
The Pulitzer finalist Vauhini Vara, quoted in the same paper, described the default machine register as “polite, predictable, inoffensive, upbeat”, and observed that great characters are not polite, great plots are not predictable, great style is not inoffensive and great endings are not upbeat. Speaking to the Christian Science Monitor in August, she identified what has actually been lost. Until AI, she said, there was an expectation that no matter what was written in a book, it had been authored by a person. That expectation was not a rule. It was infrastructure, and everything from the editorial relationship to the copyright transaction was built on top of it without anyone noticing they were standing on something.
Ten Dollars for a Sticker That Nobody Reads
So what is publishing actually doing in place of the thing it lost?
Since January 2025 the Authors Guild has operated a Human Authored certification mark, expanded in March 2026 to all authors published in the United States and to the United Kingdom in partnership with the Society of Authors. By that month more than three thousand authors had certified over five thousand titles. Registration requires third-party identity verification, a signed licence agreement and a fee of ten dollars per title.
It does not require anybody to read the book. The Guild does not analyse the manuscript. The certification operates on the honour system.
That is not a criticism of the Guild, which has been more energetic on this than any publisher and honest about what the mark does. It is a description of where the industry has arrived. Confronted with a crisis of textual authentication, the trade's flagship authenticity instrument authenticates the author's identity and takes their word about the text. Amanda Annis of Trident Media Group put the general condition accurately: the standards around it do not exist right now. The nearest thing agents have offered is Regina Brooks, president of the Association of American Literary Agents, saying after the Falade collapse that “The author-agent relationship depends on trust and honesty” and that authors have “a responsibility to be transparent about how a manuscript was created”. That is a duty of disclosure with no form, no definition and no consequence.
They could, and pieces already exist outside the Anglophone trade. The Commonwealth Foundation built an adjudication process. Ask for the drafts, the notes, the outlines, the timestamps. Judge the work through its development rather than through a classifier whose confusion matrix nobody in the room can interpret. Publish the finding. Accept that this is slower than running a detector, and accept it because the alternative has a documented false positive rate that lands on the people least able to survive it. None of that is exotic. It is roughly what a serious plagiarism investigation has always involved, and publishing has run those for a century without collapsing.
South Korea has built the other half, a disclosure taxonomy. On 29 September 2026 the Korean Publishers Association, the Writers Association of Korea and the Publishing City Culture Foundation announced voluntary principles with three levels: “Human Authored Work”, with AI confined to tasks such as proofreading or outlining; “AI-Assisted Work”, completed after human control and verification of machine material; and “AI-Generated Publication”, where that control is absent. Authors declare their level on submission, and the upper two are marked on the imprint page. It is non-binding, “a promise from the field”, and still rests on the author's word, but it asks the right question: “not whether to use the tool, but how far tasks have been delegated to AI.” American and British publishing has produced neither the adjudication nor the taxonomy.
What it requires is that somebody be willing to make a finding and stand behind it, which is precisely what nobody in the Falade case did. His agents did not conclude that he used a machine. They concluded that they could not verify that he had not, and withdrew. Minotaur did not accuse him of anything. It walked away from an asset with a title defect. Every party behaved rationally, nobody made an allegation, and a man's first novel was destroyed anyway.
Set that beside Daggermouth. In July the researchers behind the market study shared data with The Atlantic putting H.M. Wolfe's BookTok hit at about 60 per cent AI-generated or AI-assisted by Pangram's measure. Wolfe, a self-published author who had since signed a seven-figure deal, called the claim “wholly untrue” through her lawyer, adding that such accusations “should not be made on the basis of technology that is known to be unreliable”. Falade could have said the same. The difference is that Simon & Schuster said it stood behind her and the book, and the book stayed on sale. Neither outcome turned on evidence. Each turned on whether the people with obligations to the author chose to stand behind them, and the record does not say why one did and the other did not.
He still has the file. The time-stamped drafts, the written notes, the dated WhatsApp messages, a Google Docs version history in which, he says, anyone can watch the manuscript evolve: the whole apparatus of proof, assembled by an author who did not know he would need it, addressed to an industry with nowhere to send it. In September he announced a new agent, David Vigliano, and he now speaks about how writers whose first language is not English get flagged as machines, including at Nigeria's Aké Arts and Book Festival. “The machine made the accusation,” he wrote. “The human had to prove his humanity.” He has found someone to represent him. No institution has examined the file. Publishing has spent 2026 discovering that it cannot read a manuscript any more. It has not spent a single day building the thing that would let it read a writer.
Sources and References
- Wall Street Journal, “AI Has Plunged the Book Publishing Industry Into Utter Chaos”, 17 August 2026. https://www.tovima.com/wsj/ai-has-plunged-the-book-publishing-industry-into-utter-chaos/
- Suvanto, M., McGlinchey, A., Wahde, M. and Barclay, P. J., “Interpretable Text Classification Applied to the Detection of LLM-generated Creative Writing”, ICAART 2026, 12 January 2026. https://arxiv.org/abs/2601.07368
- Chakrabarty, T., Ginsburg, J. C. and Dhillon, P., “Readers Prefer Outputs of AI Trained on Copyrighted Books over Expert Human Writers”, 15 October 2025, revised 17 March 2026. https://arxiv.org/abs/2510.13939
- Chakrabarty, T., Liu, X., Ginsburg, J. C. and Dhillon, P., “Generative AI Floods and Dilutes the Market for Books”, 22 July 2026. https://arxiv.org/abs/2607.20349
- Liang, W., Yuksekgonul, M., Mao, Y., Wu, E. and Zou, J., “GPT detectors are biased against non-native English writers”, Patterns, July 2023. https://pubmed.ncbi.nlm.nih.gov/37521038/
- Moneywise, “Author Jerry Falade loses $2.4 million book deal after AI accusations”, 8 August 2026. https://moneywise.com/news/top-stories/ai-book-deal-jerry-falade-publishing-industry
- Futurism, “Major Publisher Cans $2.4 Million Book Deal After Author Was Accused of Using AI, for a Very Cynical Reason”, August 2026. https://futurism.com/artificial-intelligence/major-publisher-million-book-deal-author-accused-ai
- Christian Science Monitor, “Book publishers face rising scrutiny over AI usage by authors”, 12 August 2026. https://www.csmonitor.com/Arts-Culture/Books/2026/0812/ai-publishing-commonwealth-prize-shy-girl
- Kole, M., “After Editing Two AI-Assisted Manuscripts, I Rewrote My Client Agreement”, Jane Friedman, 13 August 2026. https://janefriedman.com/after-editing-two-ai-assisted-manuscripts-i-rewrote-my-client-agreement/
- Authors Guild, “AG Introduces New Publishing Agreement Clauses Concerning AI”, May 2026. https://authorsguild.org/news/ag-introduces-new-publishing-agreement-clauses-concerning-ai/
- Publishers Weekly, “Authors Guild Expands 'Human Authored' Certification to All U.S. Authors and Publishers”, March 2026. https://www.publishersweekly.com/pw/by-topic/industry-news/publisher-news/article/99836-authors-guild-opens-human-authored-certification-to-all-u-s-authors-and-publishers.html
- West-Knights, I., “I read the novel with suspected A.I. use. What I found was revealing”, Slate, 31 March 2026. https://slate.com/culture/2026/03/shy-girl-mia-ballard-novel-a-i-book-horror-reddit-hachette-canceled.html
- Slate, “Jamir Nazir's defense against A.I. accusations only makes the case stranger”, 7 July 2026. https://slate.com/culture/2026/07/jamir-nazir-commonwealth-short-story-prize-ai-granta-magazine-controversy.html
- The Daily Star, “Jamir Nazir wins 2026 Commonwealth Short Story Prize following AI review”, 2026. https://www.thedailystar.net/culture/books-literature/news/news/jamir-nazir-wins-2026-commonwealth-short-story-prize-following-ai-review-4214976
- Vanderbilt University Center for Teaching, “Guidance on AI Detection and Why We're Disabling Turnitin's AI Detector”, 16 August 2023. https://www.vanderbilt.edu/brightspace/2023/08/16/guidance-on-ai-detection-and-why-were-disabling-turnitins-ai-detector/
- Turnitin, “New research: Turnitin's AI detector shows no statistically significant bias against English language learners”, 2023. https://www.turnitin.com/blog/new-research-turnitin-s-ai-detector-shows-no-statistically-significant-bias-against-english-language-learners
- RNZ, “Top writers ruled out of NZ book awards due to AI covers”, November 2025. https://www.rnz.co.nz/life/books/top-writers-ruled-out-of-nz-book-awards-due-to-ai-covers
- Editorial Freelancers Association, “EFA Announces 2026 Editorial Rate Chart”, March 2026. https://www.the-efa.org/2026-editorial-rate-chart/
- United States Copyright Office, “Copyright Registration Guidance: Works Containing Material Generated by Artificial Intelligence”, 16 March 2023. https://www.federalregister.gov/documents/2023/03/16/2023-05321/copyright-registration-guidance-works-containing-material-generated-by-artificial-intelligence
- Munson, S., “I'm a novelist, cheering the $2.4M AI book deal that should open everyone's eyes”, New York Post, 16 August 2026. https://nypost.com/2026/08/16/opinion/im-a-novelist-cheering-the-2-4m-ai-book-deal-that-should-open-everyones-eyes/
- Nawotka, E. and Spratford, S., “After the Cancellation of 'Call Me, I'll Hide the Body,' What Comes Next?”, Publishers Weekly, 4 August 2026. https://www.publishersweekly.com/pw/by-topic/industry-news/publisher-news/article/100983-after-the-cancellation-of-call-me-i-ll-hide-the-body-what-comes-next.html
- Schmidt, K. and Falade, J., “EXCLUSIVE: Author Jerry Falade Reflects on Losing His Book Deal and Being Accused of Using AI”, Publishing Confidential, 17 September 2026. https://kathleenschmidt.substack.com/p/exclusive-author-jerry-falade-reflects
- Oremus, W., “Is This What Comes After AI Slop?”, The Atlantic, 27 July 2026. https://www.theatlantic.com/technology/2026/07/daggermouth-novel-bestseller-ai/688067/
- The Kyunghyang Shinmun, “Did AI only proofread, or did it also write... Publishing sector announces recommended standard for 'three-level labeling of AI use'”, 30 September 2026. https://www.khan.co.kr/en/article/202609301406027/
- Morgan Lewis, “US Supreme Court Declines to Consider Whether AI Alone Can Create Copyrighted Works”, 6 March 2026. https://www.morganlewis.com/pubs/2026/03/us-supreme-court-declines-to-consider-whether-ai-alone-can-create-copyrighted-works
- Alter, A., “Horror Novel 'Shy Girl' Canceled Over Suspected A.I. Use”, New York Times, 19 March 2026. https://www.nytimes.com/2026/03/19/books/shy-girl-book-ai.html
Tim Green UK-based Systems Theorist & Independent Technology Writer
Tim explores the intersections of artificial intelligence, decentralised cognition, and posthuman ethics. His work, published at smarterarticles.co.uk, challenges dominant narratives of technological progress while proposing interdisciplinary frameworks for collective intelligence and digital stewardship.
His writing has been featured on Ground News and shared by independent researchers across both academic and technological communities.
ORCID: 0009-0002-0156-9795 Email: [email protected]
Listen to the free weekly SmarterArticles Podcast
Support What We Do